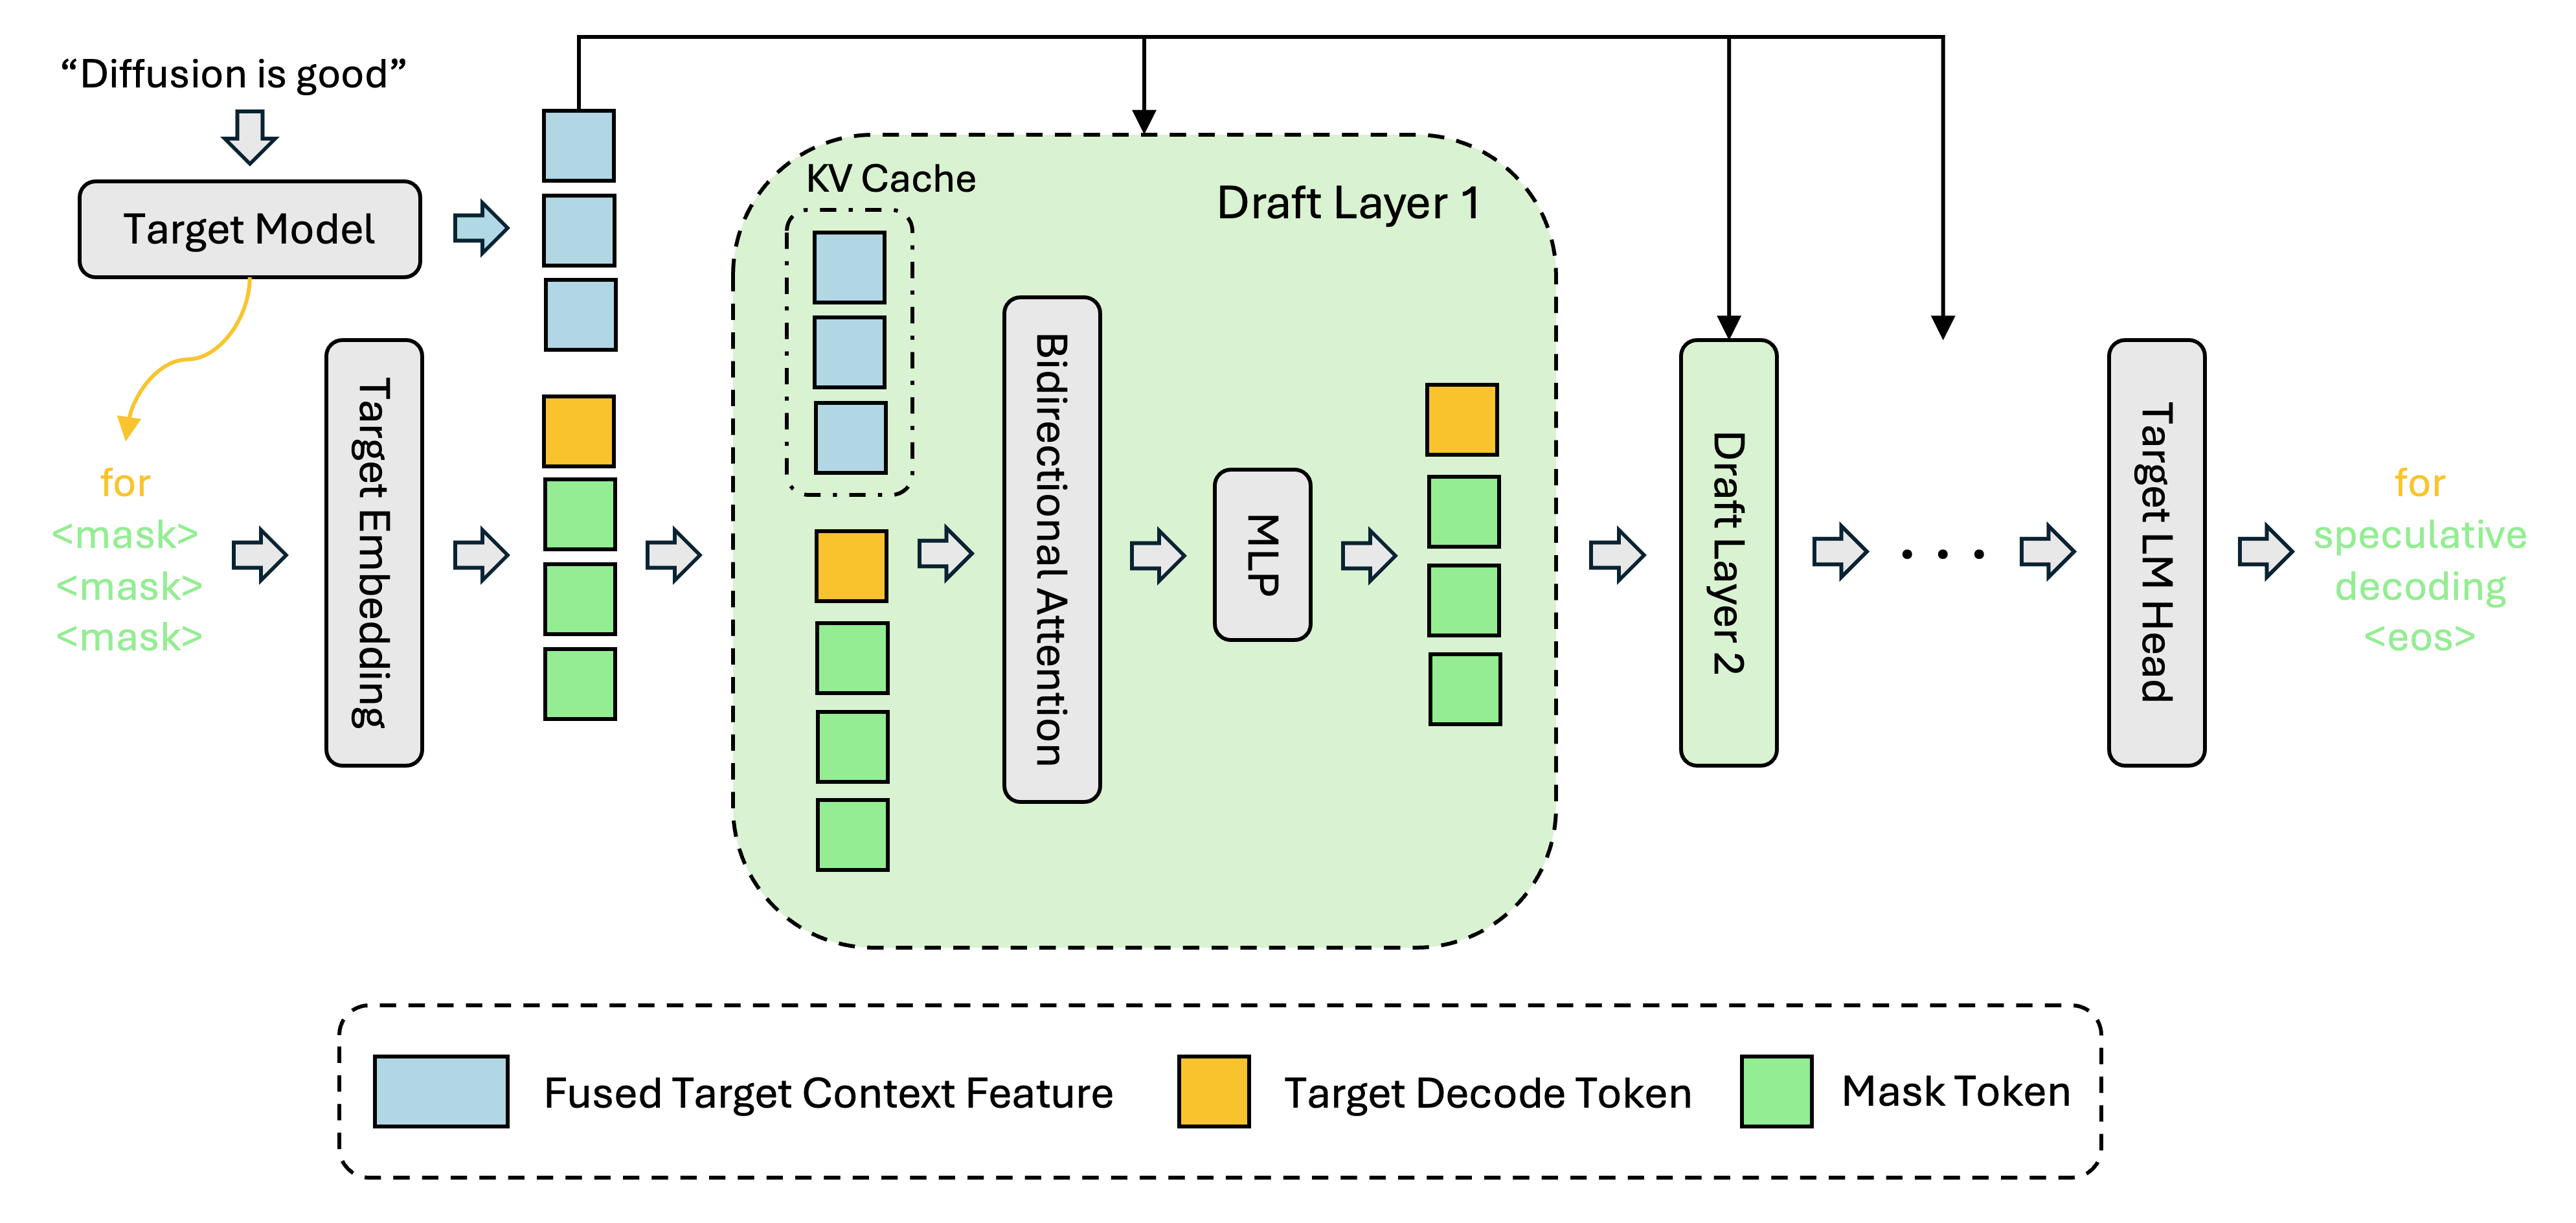
DFlash is a speculative decoding technique that uses a diffusion-based draft model to rapidly generate draft tokens.
It resolves the issue with autoregressive drafting, which is that the cost grows linearly with the speculation budget.
DFlash uses a non-causal mask so each query attends to both the verifier’s hidden states and the mask token embeddings simultaneously to produce all draft tokens at once. DFlash chooses anchor positions in the sequence, generates a block of tokens from each anchor in a single forward pass, have the target model verify the predicted blocks and accept the lognest valid prefix.
During the target model’s prefill pass, hidden states are extracted and passed through a lightweight projection that fuses cross-layer info into a compact target context feature. Whereas EAGLE-3 fuses the target hidden features with the draft model’s token embeddings and feeds them in only as inputs, DFlash instead injects the fused target feature directly into the KV projections of every draft layer, storing it in the drafter’s KV cache and reusing it across drafting iterations.